NSFW Chat & Roleplay API — uncensored LLM with persona memory
A production chat & roleplay endpoint that streams uncensored responses token-by-token from NSFW-tuned Llama 3.1, Mistral Large, Pygmalion and custom fine-tunes. Drop-in replacement for OpenAI Chat Completions — without the content refusals. Persona memory, multi-turn RP, system prompts, LoRA hot-swap and 50ms time-to-first-byte on streaming.
50ms
Streaming TTFB p50
150+
NSFW-tuned models
99.9%
Uptime SLA
<$0.40
Per 1K output tokens
TL;DR
Endpoint: POST https://api.nsfwcoders.com/v1/chat/completions — OpenAI-compatible request/response schema, SSE streaming by default, Bearer token auth, optional LoRA and persona_id parameters.
Models: Llama 3.1 70B, Llama 3.1 8B, Mistral Large, Nous Hermes, Pygmalion 12B, PsyMed RP, NSFW-tuned Llama — plus custom fine-tunes you can hot-swap per request.
Pricing: pay-as-you-go at $0.40 / 1K output tokens (cheaper on volume), credit-metered with no monthly minimums. Dedicated H100 endpoints available for $4,500/mo.
SLA: 99.9% uptime with multi-region failover; 50ms streaming TTFB p50 and 800ms non-stream p50 on the shared fleet.
A chat API that doesn't refuse half your prompts
Most chat APIs — OpenAI, Anthropic, even open-source providers behind a safety filter — silently refuse the moment a conversation turns adult. Your roleplay breaks, your character goes off-script, and your users churn. Our NSFW Chat & Roleplay API is built specifically for the adult case: uncensored LLMs fine-tuned on roleplay corpora, served with no refusal layer, with persona memory that survives long sessions.
It's OpenAI-compatible at the wire level — same chat/completions endpoint, same streaming SSE format, same tool-calling shape — so most existing SDKs work with a base-URL change. You bring your characters, system prompts and LoRA weights; we bring the GPUs, the inference engine, and the operational maturity of running adult chat for our own companion platforms.
Who uses it: companion-app teams replacing OpenAI mid-flight after a refusal storm, cam sites adding AI-driven persona chat to creator pages, dating apps prototyping AI matches, roleplay-marketplace founders, and studios generating adult scripts at scale. If you've ever shipped a chat feature and watched it break on adult content, this is the endpoint you needed from day one.
What makes it different from generic APIs: uncensored by default (not 'uncensored' as a marketing label), NSFW-tuned Llama and Pygmalion models you won't find on OpenRouter, persona memory primitives built into the API, and a provider that actually wants adult traffic on its infrastructure.
OpenAI-compatible /v1/chat/completions endpoint — drop-in SDK swap
Streaming SSE with 50ms TTFB p50 and token-level delivery
150+ NSFW-tuned models incl. Llama 3.1, Mistral Large, Pygmalion, Nous Hermes
Persona memory, system prompts, tool/function calling, JSON mode
Hot-swap LoRA per request — your fine-tunes or ours
Optional moderation hooks, CSAM pre-filter, 2257 record exports

60-day delivery
prototype to production
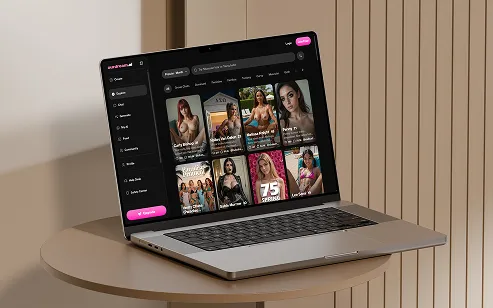
What your users actually see
A live-grade interface built on the same components we ship to production — designed for retention, monetization, and scale.
Who calls this API
AI companion apps
Replace OpenAI when refusals started costing retention — same SDK, no migration tax.
Cam & creator platforms
Add AI persona chat alongside live creators to fill dead-air hours and monetise off-peak.
Dating apps
Prototype AI matches, icebreakers and conversation prompts that don't trip safety filters.
Roleplay marketplaces
Multi-character RP with persona swaps, scene state and long context windows.
Adult content studios
Generate dialogue, scripts and scenarios at scale for video and audio pipelines.
Affiliate funnel builders
Power NSFW chatbots that convert paid traffic without the API pulling the plug mid-campaign.
Why this API vs OpenAI or Replicate
Actually uncensored
No refusal layer on adult, romantic, explicit or fantasy content — by design, not by omission.
NSFW-tuned models
Pygmalion, Nous Hermes, NSFW Llama fine-tunes — not available on OpenRouter or Anthropic.
Adult-payment-friendly
We accept adult use cases and adult-business payments; no surprise deplatforming mid-campaign.
Built-in compliance
Optional CSAM pre-filter, age-gate headers, 2257 record hooks — for processor and audit conversations.
Operated GPU fleet
Our own H100/A100 clusters with vLLM paged attention and Triton — we run the same fleet for our apps.
3 years of NSFW chat
Production-hardened on 4B+ tokens/month of real adult traffic — not a fresh wrapper.
API features what ships in the endpoint
OpenAI-compatible schema
Same /v1/chat/completions request/response shape, same SSE streaming, same tool-calling.
Streaming SSE
Token-by-token delivery at 50ms TTFB p50 — no buffering, no first-token delays.
Persona memory
Per-conversation memory_id keeps character state, history and preference graph across calls.
LoRA hot-swap
Pass lora_id per request to load character-specific fine-tunes in <500ms cold-start.
Python + Node SDKs
Typed SDKs with streaming helpers, retry/backoff and persona state management.
Signed webhooks
Conversation-end, moderation-flag and credit-low events delivered with HMAC signatures.
Credit metering
Per-request token accounting with pre-paid balance, soft and hard limits, and refund on inference errors.
Rate limits & quotas
Per-key concurrent request caps and 24h token quotas with rolling usage dashboards.
Idempotency & retries
Idempotency-Key header deduplicates retries safely; backend-level retry on transient 5xx.
Integration flow — step by step
Get API key
Sign up, verify your adult business, receive a Bearer token + sandbox key in under 24 hours.
Test in sandbox
Hit the sandbox endpoint with cURL or our Postman collection; verify streaming, persona_id and LoRA loading.
Migrate from OpenAI
Change base URL from api.openai.com to api.nsfwcoders.com — most SDKs work as-is.
Go live
Swap to production key, set rate limits, configure webhooks and credit alerts; monitor dashboards.
Tune personas & LoRAs
Upload character fine-tunes or use ours; A/B model selection and temperature per cohort.
Scale to dedicated
At volume, move to a single-tenant H100 cluster with isolated context cache and custom SLA.
How the platform is wired
NSFW Coders engineers the full stack — from model serving and GPU orchestration to the application layer, payments, moderation and analytics. Every layer is built to be audited, scaled, and swapped without re-platforming.
Model layer
Stable Diffusion, Flux, Pony, custom LoRA & 3D — served via vLLM / ComfyUI / Triton.
API gateway
Key-auth, rate limits, credit metering, signed webhooks — multi-tenant.
Application layer
Next.js / React, realtime chat, in-app feed, creator studio.
Data & safety
Postgres + Redis + vector store, CSAM scanning, age gates, 2257 logs.
4.2B+
Tokens served monthly
150+
NSFW-tuned models
50ms
Streaming TTFB p50
99.9%
Uptime SLA
Models & serving stack under the endpoint
Models
Serving
Stack
What teams build on it
AI companion chat
Girlfriend/boyfriend personas with memory, mood and explicit-option tiers.
Example: Replaced OpenAI after 30% refusal rate; tokens dropped 60% in cost.
Multi-character RP
Group roleplay with scene state, NPC personas and turn-taking.
Example: Roleplay marketplace running 8-character scenes at 4K context.
Cam-site persona chat
Creator AI twin chats fans off-peak.
Example: +22% creator-page revenue from off-hours engagement.
Adult script generation
Long-form scene scripts and dialogue at scale.
Example: Studio generating 1,200 scripts/month for video pipeline.
Dating-app icebreakers
In-app AI matches that don't trip safety filters.
Example: Pilot launched with 18+ age gate; no API warnings.
NSFW chatbot funnels
Affiliate chatbots that convert paid traffic.
Example: Chatbot on popup traffic; ROAS 1.6 at $0.05 CPC.
NSFW Coders chat API vs alternatives
| Feature | NSFW Coders | Generic OpenAI/Replicate* | Open-source self-hosted |
|---|---|---|---|
| Adult content allowed | By default | Refused | Depends on your filter |
| NSFW-tuned models | Pygmalion, NSFW Llama | Not available | DIY fine-tunes |
| Streaming TTFB | 50ms p50 | 200–400ms | Depends on infra |
| Operational burden | Zero | Zero | Full-time SRE |
| Adult-payment friendly | Yes | Often refused | N/A |
| Compliance helpers | 2257 + CSAM + age-gate | None | DIY |
| Cost at scale | $0.40 / 1K out | Higher + filters | GPU capex + ops |
| SLA | 99.9% multi-region | Provider SLA | Self-managed |
| Time to first call | Minutes | Minutes | Weeks of setup |
* Generic providers may change content policies without notice; OpenAI/Anthropic refuse adult content by default.
Built to make money on day one
Subscription tiers, token packs, pay-per-message, pay-per-view media, creator splits, affiliate payouts and tipping — wired into adult-friendly payment processors so revenue is never blocked by a sudden account freeze.
Subscription + credits
Hybrid billing that lifts ARPU without choking free-funnel conversion.
Creator economy
Multi-creator payouts, revenue share, content locks and PPV media.
Affiliate & referrals
Tracking links, first-touch attribution, automated payouts.
High-risk payments
Segpay, CCBill, Paxum, Verotel — with fallback routing.

API pricing, pay-as-you-go or dedicated
Pay-as-you-go
$0.40 / 1K output tokens
Shared H100/A100 fleet. No monthly minimums. Credit-metered with prepaid balance; cheaper on volume tiers.
- 150+ NSFW-tuned models
- Streaming SSE + tool calling
- Persona memory & LoRA hot-swap
- 99.9% SLA on shared fleet
- Python + Node SDKs
Volume / Enterprise
$4,500 / mo dedicated H100
Single-tenant H100 cluster with isolated context cache, custom SLA, dedicated model routing and on-call.
- Dedicated H100 GPU(s)
- Sub-50ms TTFB guarantee
- Custom LoRA hosting
- Single-region or multi-region
- Slack channel + 24/7 on-call
“We migrated off OpenAI in an afternoon — base URL change, done. Refusal rate went from 31% to 0 and our week-4 retention jumped 14 points.”
D. Almeida
CTO, AI companion platform (EU)
“The Pygmalion endpoint alone is worth it. We tested self-hosting and burned three weeks on ops; switching here cut our chat infra cost by 60%.”
M. Rosenstein
Head of AI, cam-site group
“Indie dev shipping an adult roleplay app solo. Their Python SDK made streaming + persona memory genuinely trivial — launched in two weekends.”
K. Osei
Indie founder
Questions, answered
Quick answers to the questions founders ask us most about this service.
Related APIs & solutions
Every service connects — most clients combine two or three of these into one engagement.
Stop fighting refusals. Ship the chat feature.
OpenAI-compatible, uncensored, NSFW-tuned. API key in 24 hours.
Tell us about your project
Free 30-min consultation. NDA on request before you share a single detail. Average reply under 4 hours.
Prefer WhatsApp?
< 4h
Avg first reply
120+
Platforms shipped
NDA
Before you talk