NSFW Content Generation API — text, image, audio in one synchronised bundle
A single endpoint that orchestrates NSFW chat LLM + image diffusion + TTS in parallel and returns a synchronised bundle: story text, scene image, character voice. Built for adult content pipelines — long-form story generation, branching script writing, character backstories and scene-by-scene media. Persona_id keeps voice, image LoRA and personality consistent across calls. From $0.02 / bundle.
3-in-1
Text + image + audio bundle
<4s
Bundle p95 latency
150+
Models orchestrated
$0.02
Per bundle (entry)
TL;DR
Endpoint: POST https://api.nsfwcoders.com/v1/content/bundle — orchestrates LLM + image + TTS in parallel; returns synchronised JSON with text, image URL and audio URL.
Models: Llama 3.1 / Mistral Large / Pygmalion for text; SDXL / Flux / Pony for images; XTTS v2 / StyleTTS 2 for audio — plus NSFW-tuned variants.
Pricing: from $0.02 / bundle (entry text+image+audio), itemised per modality; volume tiers and dedicated pipelines available.
SLA: <4s bundle p95 latency on shared fleet, 99.9% uptime with multi-region failover; partial-failure retry preserves successful modalities.
Stop stitching three APIs into one brittle pipeline
Building an adult content pipeline today usually means calling a chat LLM, then piping output into an image API, then piping image+script into a TTS API — three round-trips, three error modes, three bills, and zero guarantee the voice matches the character the image depicts. Our NSFW Content Generation API collapses that into one endpoint: send a prompt and a persona_id, get back synchronised text + image + audio.
The orchestration layer runs the LLM, image diffusion and TTS in parallel, binds them via a shared persona_id, and returns a bundle. Story scripts stay in character across scenes; image LoRA stays consistent across shots; voice stays consistent across clips. Partial failures retry only the failing modality — your successful image isn't regenerated because the TTS endpoint timed out.
Who uses it: companion apps generating in-chat image+voice messages from a single prompt, content studios producing synchronised story+image+audio for adult audiobooks and visual novels, roleplay marketplaces bundling character intros, and affiliate funnels generating complete landing-page content bundles (story + hero image + voiceover) in one call.
What makes it different: it's not three APIs with a client-side glue layer — it's one orchestration engine with shared persona state. The character whose voice you heard in scene 1 is the same character whose face you see in scene 50. The credit-metered bundle pricing makes it cheaper than calling three separate endpoints, and the partial-failure retry model means you don't pay for redundant regeneration.
One endpoint: LLM + image + TTS orchestrated in parallel
Synchronised bundle: text, image URL, audio URL returned together
persona_id binds voice + image LoRA + personality across calls
Long-form story/script generation with branching dialogue trees
Character backstories, scene descriptions, story arcs from one prompt
Partial-failure retry: successful modalities preserved, only failing one re-run

60-day delivery
prototype to production
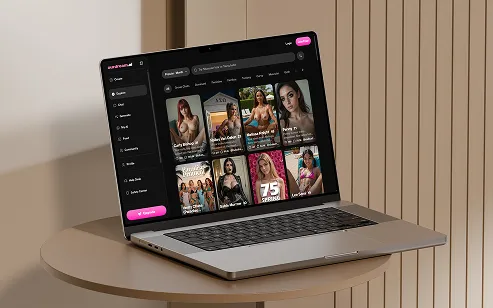
What your users actually see
A live-grade interface built on the same components we ship to production — designed for retention, monetization, and scale.
Who calls this API
AI companion apps
In-chat image + voice messages from a single prompt — no client-side stitching.
Adult audiobook studios
Synchronised story + scene image + narration audio in one call for pipeline speed.
Visual novel studios
Branching scene scripts with consistent character voice and image across all branches.
Roleplay marketplaces
Character intros with synchronised portrait + backstory + voice sample.
Affiliate funnel builders
Generate complete landing-page bundles: story + hero image + voiceover in one call.
Adult game studios
Scene-by-scene media generation with consistent persona_id across the whole game.
Why this multi-modal API vs stitching three
One call, three modalities
Single endpoint, single bill, single error model — no client-side orchestration glue.
Synchronised persona_id
Voice + image LoRA + personality bound across calls — character consistency for free.
Parallel orchestration
LLM + image + TTS run in parallel; <4s bundle p95 vs 12s+ sequential calls.
Partial-failure retry
Successful modalities preserved; only failing modality re-runs — no redundant regeneration cost.
Adult-tuned models
Pygmalion, NSFW Llama, Pony, XTTS-tuned — models generic multi-modal APIs don't expose.
Cheaper than three APIs
Bundle pricing beats calling OpenAI + Replicate + ElevenLabs separately for the same output.
API features what ships in the endpoint
Multi-modal bundle
Single request returns JSON with text, image URL, audio URL — all synchronised to one persona_id.
Parallel orchestration
LLM + image + TTS run in parallel internally; <4s bundle p95 vs 12s+ sequential.
persona_id consistency
Voice, image LoRA and personality bound across calls; character stays the same in scene 1 and scene 50.
Long-form story gen
Submit a story arc; receive chapter-by-chapter text + scene image + narration audio.
Branching script gen
Dialogue trees with consistent character voice across all branches; supports choice-state.
Character backstories
Generate persona backstories, image LoRA and voice profile from a single character brief.
Partial-failure retry
Successful modalities preserved; only failing modality re-runs with credit refund on failure.
Per-modality control
Toggle modalities per request (text-only, image-only, audio-only, or all three) — same endpoint.
Webhooks + batch
Async bundle completion via signed webhook; batch submission for bulk content pipelines.
Integration flow — step by step
Get API key
Sign up, verify business, receive Bearer token + sandbox key with sample persona set in 24 hours.
Configure personas
Create persona_ids with voice, image LoRA and personality profile; or use our preset library.
Test bundle
Submit a story prompt; verify synchronised text + image + audio and persona consistency.
Integrate pipeline
Use Python/Node SDK with bundle helpers; wire webhook for async batch pipelines.
Go live
Swap to production key; configure per-modality retry policy, rate limits and credit alerts.
Scale to dedicated
At volume, move to dedicated multi-GPU pipeline with custom persona hosting and SLA.
How the platform is wired
NSFW Coders engineers the full stack — from model serving and GPU orchestration to the application layer, payments, moderation and analytics. Every layer is built to be audited, scaled, and swapped without re-platforming.
Model layer
Stable Diffusion, Flux, Pony, custom LoRA & 3D — served via vLLM / ComfyUI / Triton.
API gateway
Key-auth, rate limits, credit metering, signed webhooks — multi-tenant.
Application layer
Next.js / React, realtime chat, in-app feed, creator studio.
Data & safety
Postgres + Redis + vector store, CSAM scanning, age gates, 2257 logs.
<4s
Bundle p95 latency
3-in-1
Text + image + audio
150+
Models orchestrated
99.9%
Uptime SLA
Models & orchestration stack under the endpoint
Models
Orchestration
Stack
What teams build on it
Companion in-chat media
One prompt → character voice note + matched selfie, returned together.
Example: Companion app shipping 1.2M bundles/month in-chat.
Adult audiobook pipeline
Story + scene image + narration in one call per chapter.
Example: Studio producing 30-chapter audiobooks in 4 hours.
Visual novel scenes
Branching script + character sprite + voice line per scene.
Example: VN studio shipping 2,000 voiced+imaged scenes.
Character marketplace
Sell character bundles: portrait + backstory + voice sample.
Example: Marketplace with 1,500 character bundles sold.
Affiliate lander bundles
Story + hero image + voiceover in one call per lander.
Example: Affiliate producing 80 complete landers/day.
Game scene cinematics
Scene-by-scene media with consistent persona across the game.
Example: Adult game shipping 12 hours of voiced content.
NSFW Coders content API vs stitching three
| Feature | NSFW Coders | Stitching three APIs* | Open-source self-hosted |
|---|---|---|---|
| Single endpoint | One call | Three calls + glue | DIY orchestrator |
| Persona consistency | Bound across modalities | Manual mapping | DIY state |
| Bundle latency | <4s parallel | 12s+ sequential | Depends on infra |
| Partial-failure retry | Per modality | Re-run all | DIY |
| Adult-tuned models | Pygmalion, Pony, XTTS | Generic only | DIY fine-tunes |
| Operational burden | Zero | Glue code maintenance | Full-time SRE |
| Cost at scale | $0.02 / bundle | Three bills | GPU capex + ops |
| Long-form story gen | Built-in | Manual chaptering | DIY pipeline |
| SLA | 99.9% multi-region | Three SLAs to chase | Self-managed |
* Stitching three APIs (OpenAI + Replicate + ElevenLabs) requires client-side orchestration, three bills, and zero persona consistency.
Built to make money on day one
Subscription tiers, token packs, pay-per-message, pay-per-view media, creator splits, affiliate payouts and tipping — wired into adult-friendly payment processors so revenue is never blocked by a sudden account freeze.
Subscription + credits
Hybrid billing that lifts ARPU without choking free-funnel conversion.
Creator economy
Multi-creator payouts, revenue share, content locks and PPV media.
Affiliate & referrals
Tracking links, first-touch attribution, automated payouts.
High-risk payments
Segpay, CCBill, Paxum, Verotel — with fallback routing.

Content API pricing, per bundle or dedicated pipeline
Pay-as-you-go
$0.02 / entry bundle
Text + image + audio bundle on shared fleet. Itemised per modality; partial-failure refund. Volume tiers drop 30–50%.
- 3-in-1 bundle (text+image+audio)
- 150+ orchestrated models
- Persona consistency across calls
- Per-modality retry & refund
- 99.9% SLA on shared fleet
Dedicated pipeline
$7,500 / mo dedicated multi-GPU
Single-tenant multi-GPU pipeline with custom persona hosting, dedicated model routing and on-call for high-volume studios.
- Dedicated H100 + A100 cluster
- Custom persona hosting
- Sub-3s bundle SLA
- Multi-region failover
- Slack channel + on-call
“We were burning 12s per scene stitching OpenAI + Replicate + ElevenLabs. This API cut it to 3.4s and the character actually looks and sounds the same across episodes.”
P. Castellanos
Founder, adult audiobook studio
“Persona consistency was the killer feature. Our visual novel characters used to drift between chapters — now they don't, and we ship 3x faster.”
H. Yamamoto
Lead dev, adult VN studio
“Affiliate funnel bundle: story + hero image + voiceover in one call. We went from 4 hours to 12 minutes per lander.”
D. Ferreira
Media buyer → owner
Questions, answered
Quick answers to the questions founders ask us most about this service.
Related APIs & solutions
Every service connects — most clients combine two or three of these into one engagement.
One endpoint. Three modalities.
Synchronised text + image + audio, persona-bound. API key in 24 hours.
Tell us about your project
Free 30-min consultation. NDA on request before you share a single detail. Average reply under 4 hours.
Prefer WhatsApp?
< 4h
Avg first reply
120+
Platforms shipped
NDA
Before you talk